Artifacts
Interactive things I've made with LLMs that I found useful for learning complicated concepts.
| Nov 09, 2026 | Does Adam favor a basis? Gradient descent doesn't care which basis your parameters are written in, but Adam does. Why that happens, and how it ties into the outlier features you see in transformers trained with Adam. |
|---|---|
| Nov 08, 2026 | Chaos, and why retraining is never the same An intro to chaos theory (the Lorenz system, Lyapunov exponents, the butterfly effect) starting from basic calculus, and why training a neural net behaves like a chaotic system. |
| Oct 25, 2026 | Why H100 has four NVSwitches How the 8 GPUs in an H100 server are wired together over NVLink, and why it takes four NVSwitches when B200 gets by with two. |
| Oct 25, 2026 | InfiniBand field guide An intro to InfiniBand, the network that connects GPUs in big training clusters, for people with no networking background. How data gets from one GPU to another, why the network never drops packets, and how that differs from Ethernet. |
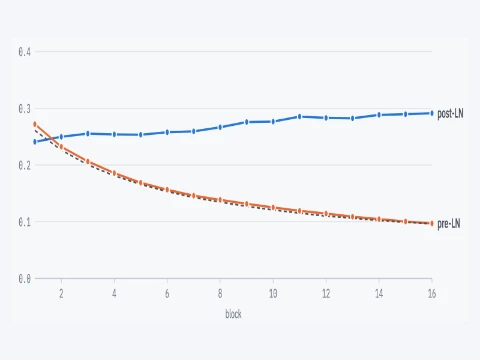
| Oct 03, 2026 | Pre-LN vs post-LN gradients How where you put LayerNorm in a transformer changes the gradients at each layer, and why that means post-LN needs learning rate warmup while pre-LN mostly doesn't. |
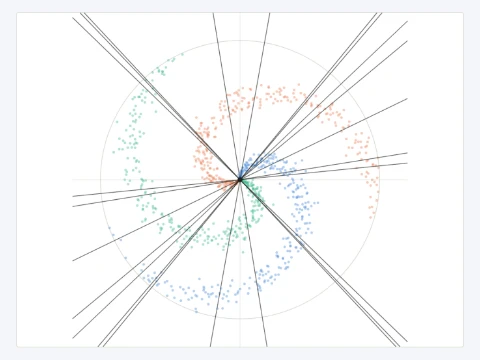
| Oct 01, 2026 | Why do ReLU nets need a bias? Why ReLU networks need bias terms. Without them every decision boundary has to pass through the origin, which limits what even a very wide net can learn. |